· Aiden Malloy · AI in Practice
AI Accuracy on Financial Documents: 18 Models Tested on a 60-Page 10-Q
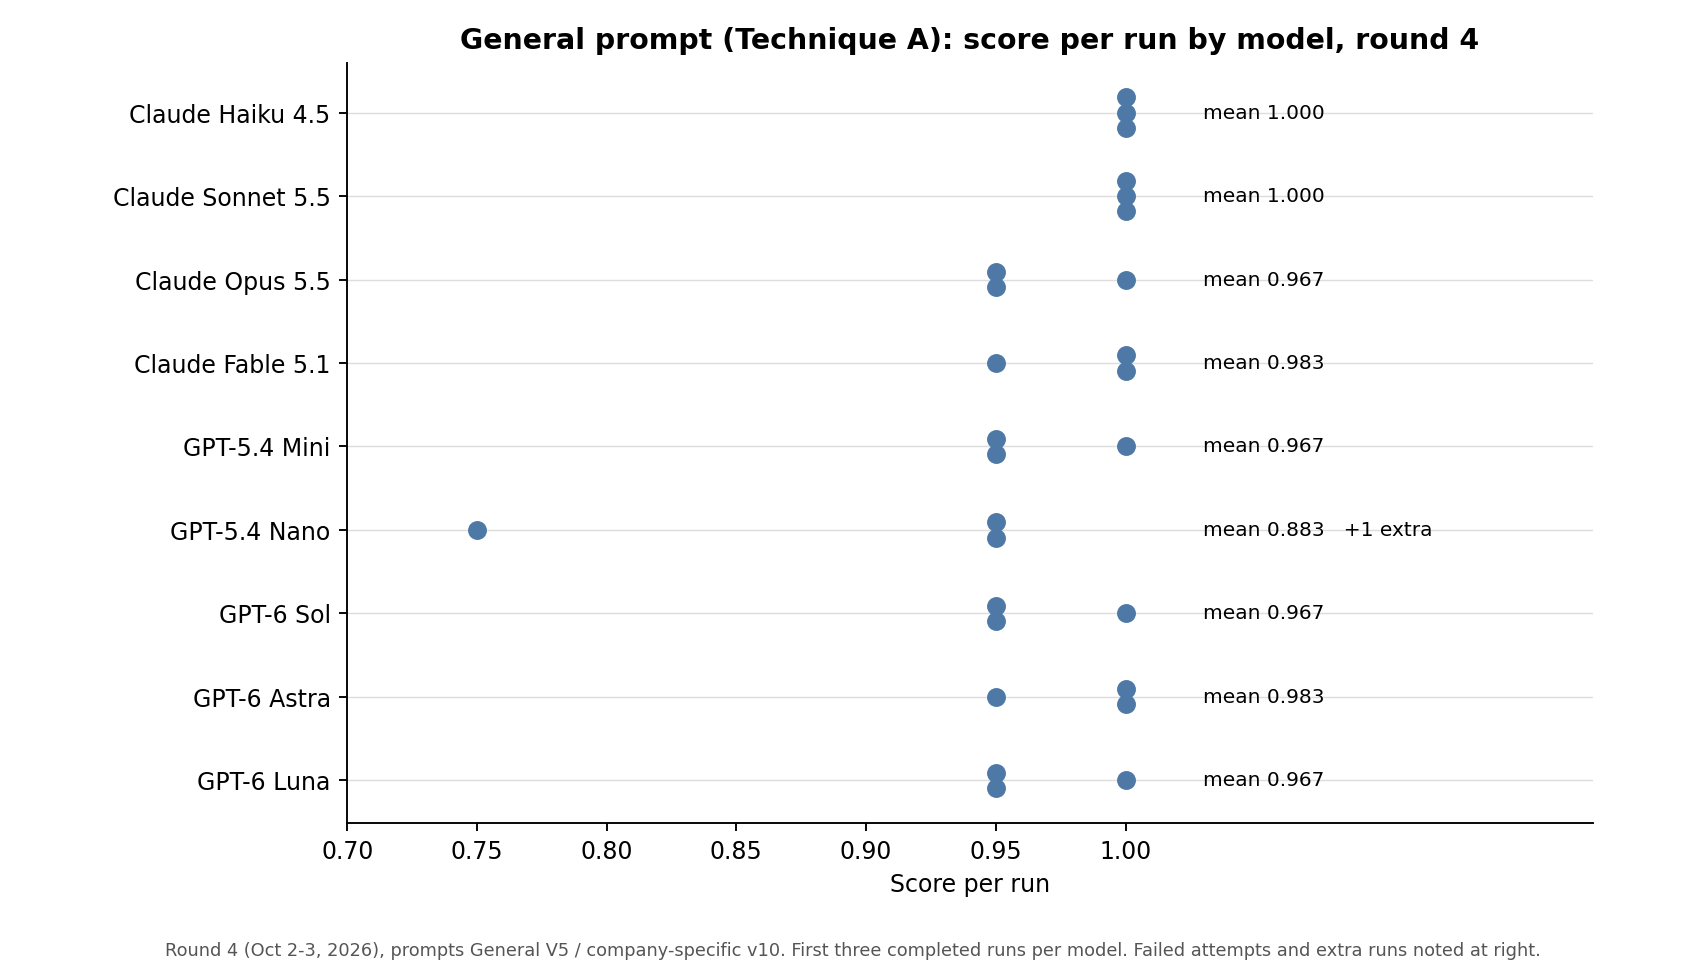
We tested 18 large language models (LLMs) on extracting 20 figures from a 60-page 10-Q, scoring accuracy, cost per run, response time, and consistency across four rounds. Claude Haiku 4.5 scored perfectly on every final run at $0.05–$0.15 per run; prompt wording mattered more than model price. For investment and advisory firms evaluating AI for document work.